What a Series A AI Startup's Answers About Compute Budget and Model Ownership Tell You
Two questions about compute and ownership reveal a startup's real economics.
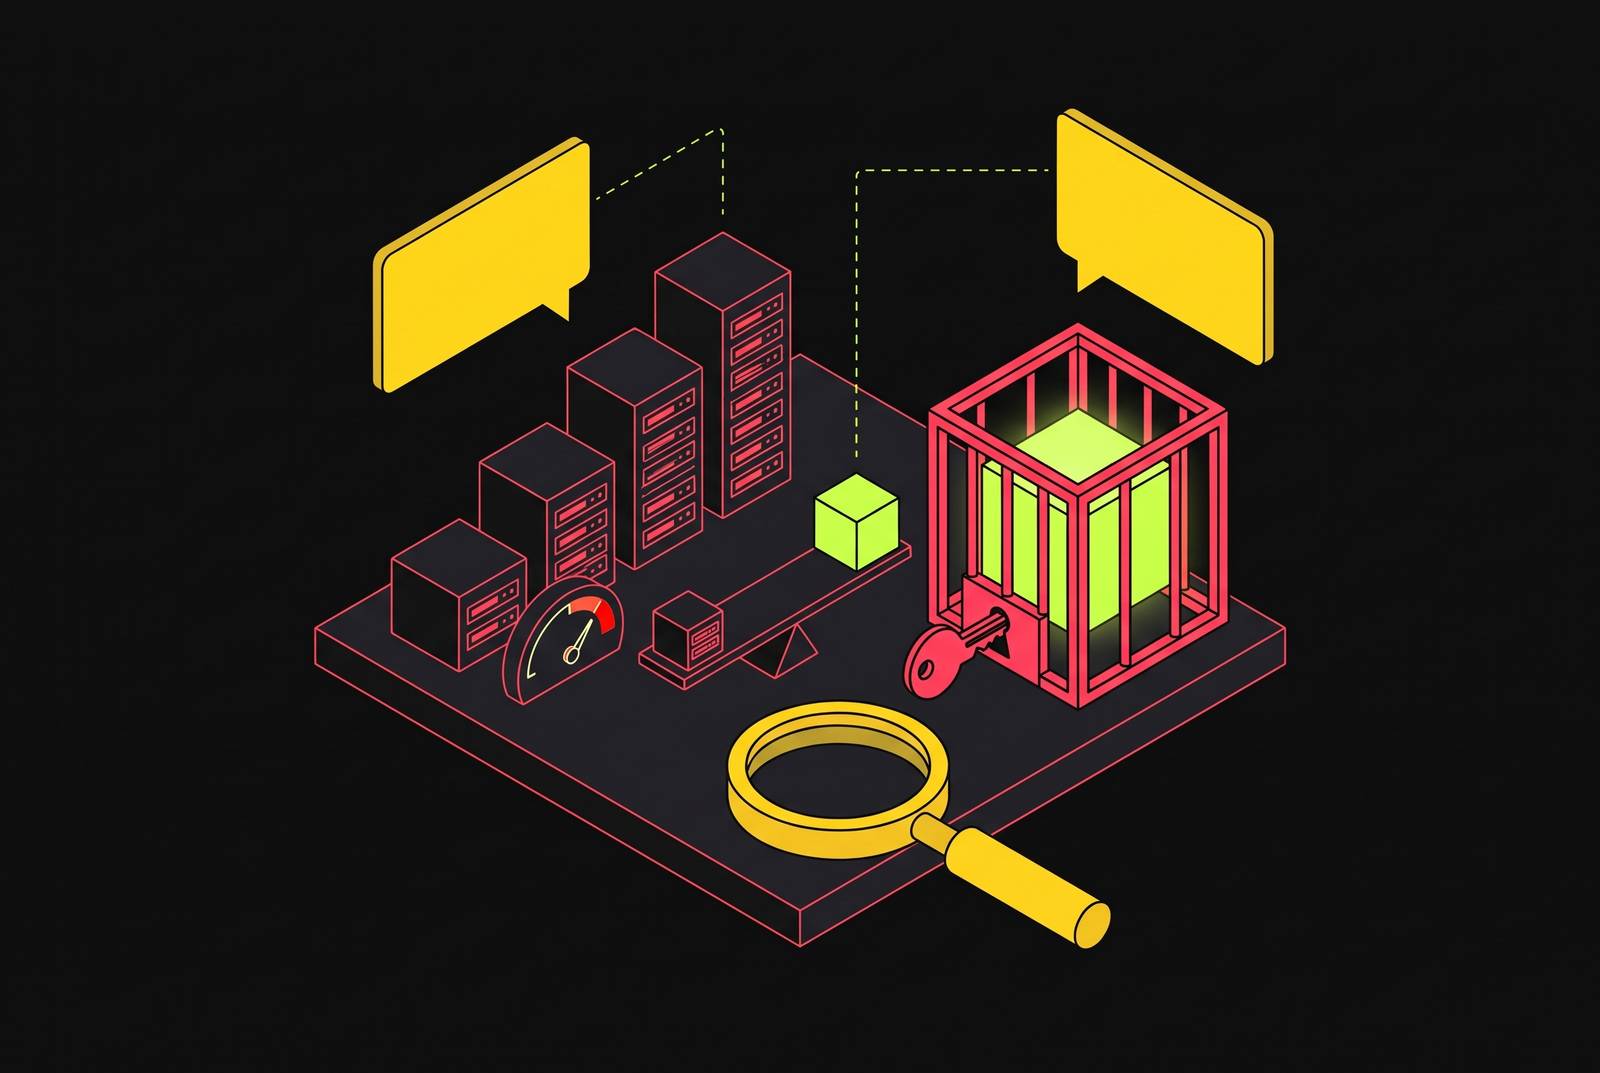
To evaluate an ML engineering offer from a Series A AI startup, ask how it allocates compute budget and who owns the model, training data, and outputs. The answers show whether the business knows its costs and has something that competitors cannot easily copy.
Why compute budget and model ownership are the two questions that reveal a Series A AI startup's real economics
Series A funding underwrites early product-market fit, including real retention, unit economics that point somewhere, and a repeatable acquisition channel. An engineer who probes the cost structure and model provenance is rerunning that investment assessment from the employee’s seat. The investment includes years of work as well as money. Joining a company with little behind its technology can use up those years without giving the engineer the experience the role promised.
A polished demo and an attractive equity grant cannot settle that assessment. The evidence comes from the choices behind the architecture, cost models, and records of where the data and models came from. Candidates with demonstrable 0-to-1 shipping experience have leverage to ask for it before signing. Compute reveals what delivering the product costs, while ownership reveals what the company controls and can defend, so the two function as a single diagnostic.
What compute budget actually measures, and why the classic software cost model breaks for AI products
Every model request has an inference cost, whether the company pays a provider or runs the model on its own infrastructure. That cost breaks the assumption behind traditional software margins that marginal cost is near-zero. More use means more work for the model. Unless pricing covers that work, growth can leave gross margins well below those of traditional software, as the company spends more on inference when the product scales.
Multi-agent systems make the relationship harder to manage because memory and tool use compound token consumption and latency. A simple per-seat subscription may not cover those costs. The subscription price stays the same while usage changes. Many AI startups initially priced subscriptions without modeling token consumption, then had to reprice mid-flight, damaging customer trust and driving churn. Pricing is therefore part of the architecture’s economic viability.
If serving customers creates a recurring compute expense, what does the founding team know about that expense and its effect on margin? A total cloud bill is not enough. The answer needs to connect the work customers do to what the company spends serving them.
How to read the compute budget answer — and what a prepared team can explain that an unprepared one cannot
The team should provide inference cost per active user, a model of how gross margin changes with scale, and the assumptions behind it. A prepared team can explain all three. It can also distinguish high-volume classification from customer-facing chat and from low-latency or low-volume tasks, rather than treating every request as economically interchangeable. Those differences should inform the margin floor the company needs at its planned scale.
Listen to the verbs as well as the numbers. Active answers name who chose a model tier, which workload it is for, and why the business can afford it. Passive answers leave it unclear who made the choices. Promises that costs will be optimized later do not establish who understands the problem now, and the missing work may become the new hire’s assignment.
compute is basically a rounding error” is a warning. At meaningful scale, it suggests the team has not modeled the expense or is deflecting. Model prices from a single vendor can range roughly fivefold from the smallest to the frontier tier, so the tier the team chooses affects its margin. For robotics, edge inference, and automotive products, the constraint changes. Compute becomes a fixed hardware envelope, and the team needs to explain quantization and pruning trade-offs within it.
What model ownership actually means — the three chains of title an engineer needs to trace
Model ownership divides into three chains of title, covering the weights, the training data, and the outputs. The company needs to explain what it owns and what rights it has for each. A company’s answer about its weights, for example, does not establish the provenance of the data used to train them or its rights over the resulting outputs.
For a candidate, the practical task is to trace each chain rather than accept a blanket claim that the technology is proprietary. The team should explain where the training data came from and who owns data governance. A named person should be responsible for it. If nobody can identify that person, governance does not exist in practice, whatever the company says about its policies.
Synthetic data adds a separate validation question. Ask how the team tests whether it covers real-world edge cases, rather than assuming that generating data makes it fit for use. A cleaned public dataset is not a proprietary training moat. Undocumented provenance also creates legal and financing risk, so this is not merely a question about technical neatness. Financing delays can reach the runway that supports the job.
Why heavy API reliance is not automatically a red flag — and when it actually is
Using third-party foundation models is not, by itself, evidence of a weak business. Most Series A companies are right not to train a model from scratch. Training can be an expensive way to build a depreciating asset, because frontier model quality improves continuously. The cost of obtaining that ownership has to be judged against what it lets the product do.
Fine-tuning on proprietary data, retrieval over a company-owned corpus, and deep workflow integration can deliver much of the defensibility benefit at a fraction of that cost. Distribution and proprietary data loops can be more durable than a temporary lead in model capability. The diagnostic therefore needs to separate dependency from replaceability.
A product that gets all its value from an interface over someone else’s model, with no proprietary data loop, workflow integration, or customer switching cost, is a warning sign. That is a business the provider can replicate as a feature. For candidates, the sharper question is what becomes harder to copy as customers use the product. A strong answer describes a data flywheel or workflow lock-in. A weak answer describes the interface.
How to ask about provider dependency and what a contingency-ready team can tell you
Even a defensible product needs a plan for its dependencies. Ask for the documented list of models and providers, then ask what changes if pricing, availability, or API terms shift. A prepared team can name its top two foundation model providers and their fallbacks. It has modeled at least two scenarios and can identify the person responsible for contingency work.
The distinction is between acknowledging exposure and preparing for it. A team that has done the work can connect a provider change to the product and its costs. Ownership makes that answer more credible. Without someone explicitly responsible, the candidate has no clear account of who will turn a fallback into an operational plan.
For companies selling into regulated markets, provider dependency also has a compliance dimension. The EU AI Act’s general-purpose AI governance rules applied from August 2025, and most of its rules apply from August 2026. Rules for high-risk systems apply from December 2027 for Annex III systems or August 2028 for Annex I products. That requires both engineering and legal answers. To connect the contingency discussion to actual practice, ask how the team diagnosed its last production model failure.
What the eval infrastructure reveals — and why it is the third signal the first two questions unlock
That failure discussion should lead to evidence of how the team detects degraded model behavior. Eval harnesses, drift detection, and version-controlled retraining triggers show whether costs and dependencies are actively managed. Performance claims need a way to be tested. Request the eval harness, model registry, and version-control tools to distinguish measured performance from assertions about it.
A strong account of a production failure traces the error to the training data and code version behind it. Release-only benchmarks leave a gap in that account. So does a claim that the model has never failed, because it leaves open whether anyone could detect a failure at all. The team should explain how often models are retrained and what triggers those cycles. Retraining itself costs compute, so the answer connects operational discipline back to the original budget question.
How to evaluate an ML engineering offer based on the role you are being hired for
An ML engineer will work inside the cost structure every day, while an AI engineer deploying pre-trained models needs to understand provider dependency before it becomes an operational problem. The title alone does not define the assignment. The answers should show which decisions the person will own and which constraints they will inherit.
For a research engineer, ownership questions establish whether there is anything proprietary to research. Most Series A AI startups need a research engineer rather than a pure research scientist, unless research output is the core product, as at a foundation model company. If the company has nothing proprietary to investigate, a research scientist role is likely misclassified, and the candidate needs to understand the work behind the label.
Founding engineers face a different burden because there is no precedent or inherited infrastructure for these decisions. From the company’s side, a useful evaluation asks the candidate to design a proof-of-concept architecture covering RAG design, quality measurement, an eval dataset, and cost per query. That exercise joins technical choices to economic consequences. The exercise also helps make clear what work the company is paying for. At Series A, a founding engineer and a staff ML engineer have different equity and base compensation profiles, so the offer must be read against the actual assignment.
Putting the diagnostic together — what good answers, bad answers, and deflections each signal about the business
Good answers form a connected account of the business. Inference cost per active user supports the margin model, provider fallbacks address dependency, and traceable data provenance has a named governance owner. A proprietary data loop explains what becomes harder to copy with use. Eval infrastructure then provides evidence that the team can detect when its assumptions stop holding.
Weak answers break those connections. Deferred optimization leaves the margin claim unsupported, passive language obscures responsibility, and an interface-only value proposition leaves little to defend. Deflection is evidence that a team staying vague about cost either does not understand its economics or hopes the candidate will not press. Both indicate operational immaturity at a stage when these questions should already have been modeled.
For the engineer, the result is a better basis for negotiating the offer and judging the risk of a multi-year commitment. Without that basis, an attractive package can mask a mispriced risk or a missed warning. The evaluation runs in both directions. Companies that can handle this conversation well can close strong candidates faster, while candidates show how they connect systems to economics.