The Vetting Questions a Talent Network Should Answer Before It Sends an ML Engineer a Single Role
A good ML engineer match depends on vetting the role, the engineer, and the company.
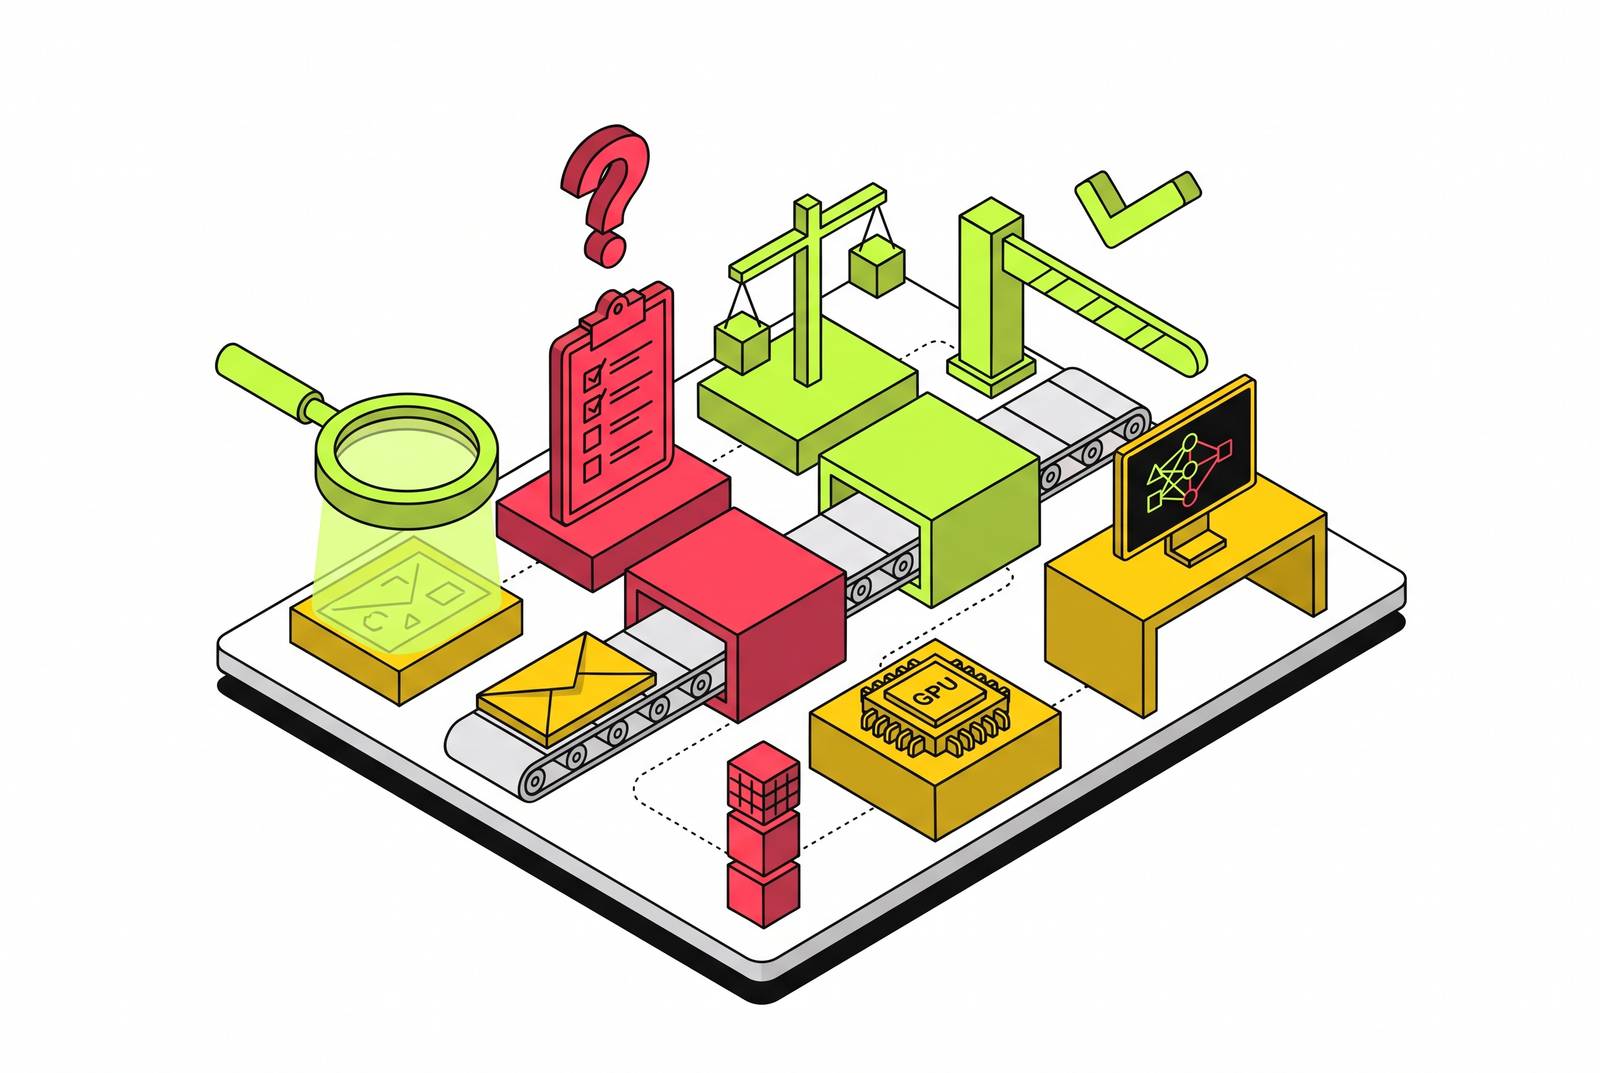
Before sending a role for ML engineer career opportunities at Series A and Series B AI startups, a talent network should find out what the work is, test production judgment, and vet the company. The funding stage alone cannot show whether the role is a good fit. A useful network also explains how quickly a match can reach a salary bid, because an engineer’s time is the resource a bad introduction cannot return.
Why the ML talent market punishes networks that guess at fit
Demand for engineers who can build, deploy, and maintain AI-powered systems has grown apart from the broader tech hiring market, which has contracted. That split makes indiscriminate matching especially costly for ML engineers. Volume is not evidence of a good match. For the engineer, every irrelevant conversation competes with a process that could already be moving toward an offer.
The hardest engineers to find are those who own the full model lifecycle, from training through production monitoring, and they rarely apply for jobs. A network waiting for inbound applications is therefore poorly placed to reach them. But access alone does not establish judgment. The network must distinguish someone who can run a Jupyter notebook from someone who can deploy scalable, fault-tolerant models. Before an engineer spends time on an introduction, the network owes them evidence that it understands that distinction and has applied it to the role.
What "ML engineer" actually means before a network can match one
The first distinction starts with the job title. “ML engineer” often stands in for work that belongs to at least five different roles, whose practitioners are not interchangeable. A useful taxonomy separates them by proximity to model training and by whether the work centers on originating ideas or operating systems. Titles alone cannot make those distinctions reliably. The network has to identify what the person will actually do.
A Research Scientist works closest to the frontier, develops novel methods, and almost always holds a PhD with first-author papers at top venues. A Research Engineer runs experiments at scale and increasingly co-authors papers, but does not need a doctorate. An ML Engineer is in charge of training, deployment, monitoring, and retraining in production. An ML Infrastructure or platform engineer builds the distributed-training and GPU systems that support the others. An Applied AI Engineer ships products on foundation-model APIs and may never train a model from scratch.
Daily work is the quickest test of fit. A research scientist is poorly matched to a job dominated by shipping features, while an ML engineer will be frustrated by research with no deployment path. An applied AI engineer instead works on fast iteration using models that already exist. Those differences show whether the job has the work an engineer wants, beyond the familiar terms on their resume. Sending a research-scientist-caliber candidate to a Series A product startup, or an applied AI engineer to a foundation model lab, fails that test before the first conversation.
How a network should verify that an engineer is production-ready, not resume-keyword-ready
Once the network can name the role, it needs a way to test for it. Screening credentials and framework names does not establish whether an engineer can keep a model useful in production. A job board can find matching words. The network’s added value has to come from successive tests of judgment, then AI-native fluency, and finally whether the work holds up in practice.
Data drift and overfitting are specific failure modes that a screening process can probe. The useful signal is how the engineer explains a model’s poor performance and reasons toward a response. Randomly toggling hyperparameters does not show that understanding. A network should be able to explain how its assessment separates a diagnosis from a guess.
The same distinction applies to familiarity with a framework. Importing PyTorch is not the same as understanding the computational graphs and memory management needed to run models efficiently. Cloud and MLOps fluency also separates deployment experience from prototyping experience. AWS, GCP, Azure, MLflow, Weights & Biases, and pipeline orchestration appear in job requirements because production work extends beyond training. But naming those tools is still not enough. The vetting method must test whether the engineer understands the work behind them.
For founding and early-stage roles, that judgment needs a further probe. An intentionally vague technical problem, without a clean specification or clean data, reveals how an engineer handles ambiguity. The useful behavior is movement toward a prototype that exposes constraints, followed by an explanation of the tradeoff behind a good-enough solution. Waiting for the specification to sharpen reveals something different. This is a concrete way to test agency without confusing it with confidence, credentials, or a polished recruiter conversation.
The network then needs to test AI-native fluency on its own. In 2026, an AI-native engineer briefs the agent before it writes, runs tests before accepting its output, and can explain why a plausible AI-generated solution was discarded. Acceptance is not the same as evaluation. A network that looks at these choices learns more than one that only asks whether the candidate uses AI tools.
That assessment also needs to cover LLM orchestration, agent frameworks, vector databases, and RAG architecture explicitly. These should not be optional extras in screening for AI-native work. The network needs to distinguish familiarity from the ability to make and defend technical choices. Its explanation of the assessment should make that distinction visible to the engineer.
The final gate is a work sample or paid trial. A trial tests whether the work holds up under real conditions, the hardest claim to fake. PostHog’s official handbook describes its SuperDay as a paid full day of work, with a task generally designed to exceed what one person can finish in that time. The scope is deliberate. It lets the team assess prioritization and the ability to get things done.
That example shows why the work sample belongs at the end of the sequence. Earlier assessments can establish how an engineer reasons and uses tools, while the trial exposes those choices in the work itself. A credible network should be able to point to that evidence. If its account ends with a recruiter’s impression, it has not demonstrated production readiness. The engineer deserves to know which claim the screening actually supports.
Why vetting speed is part of the vetting itself
Elite ML engineers run parallel hiring processes, and the first credible offer with a salary bid attached tends to close the search. A network that spends weeks on multi-stage screens can lose the window in which its match was possible. Delay defeats the purpose of the screening. This is not an argument for weaker tests, but for completing meaningful tests at the pace the market requires.
The network should therefore give a concrete screening-to-introduction timeline and explain how it reflects the dropout rate of the candidates it handles. An average drawn from a broader market that includes passive job boards does not answer that question. The engineer’s practical question should go further. “From the moment you have a matched role, how long until I receive a salary bid?” That interval connects the network’s assessment to an outcome, rather than measuring how long it can keep someone occupied.
What a network must know about a Series A or Series B AI startup before recommending it
Vetting has to work in both directions. A network that tests engineers carefully but recommends companies indiscriminately leaves the engineer exposed to a different kind of mismatch. The company’s stage, including Series A and Series B, funding, and technical environment provide context for assessing fit and can make a technically relevant role wrong for the person. The network must know what the company needs now and whether the engineer can do that work there.
Most Series A and Series B AI startups need an ML engineer who can ship immediately, rather than a research scientist, unless the core product is a foundation model. For an early-stage company without an existing ML team, the default should be an ML engineer. That role can demonstrate business value without requiring the operational infrastructure a research scientist needs to be productive. Hiring order changes what the job demands. A network should know whether the engineer will join an ML team that is already there or be expected to get production work up and running.
Technical maturity makes that distinction more concrete. The network should already know whether the company calls foundation-model APIs, fine-tunes models that already exist, or trains models from scratch. Each kind of work comes with a different engineering environment, and different people will do well in each. They are not interchangeable versions of “working in AI.” Without that information, an engineer cannot tell whether the opportunity fits their experience or the daily work they want.
A company without MLOps tooling, a data pipeline, or a culture of model monitoring can set an engineer up to fail regardless of individual ability. The network owes the engineer a clear, honest account of what is missing before it makes the introduction. It should not let a title conceal them. For someone evaluating an early-stage AI startup offer, the relevant question is whether the company’s actual infrastructure supports the responsibilities attached to the role.
Interview transparency is another concrete part of that account. AI engineering interviews differ widely from company to company in how they mix LeetCode, system design, and project-based assessments. A network should know whether a particular process uses live coding, take-home projects, or paid trials, and whether AI tools are permitted. That knowledge saves the engineer from preparing blindly.
The questions an ML engineer should put to any talent network before engaging with it
The practical test is a direct conversation before accepting introductions. An engineer can start by asking which of the five archetypes the role fits and how the network determined that. The answer should describe the work, distinguishing research, experiments, production ownership, infrastructure, and products built on existing models. Hedging at this point suggests that the network has not resolved the first matching question.
The engineer should then ask how the screening method works. What does it test beyond resume keywords, and does it examine production failure modes such as data drift and inference latency? Does it assess LLM orchestration, RAG, and agent frameworks explicitly? A recruiter phone screen is not enough. The network should also be able to identify the work sample or paid trial that supports its judgment, especially when it claims to recognize builders who can operate under ambiguity.
The engineer should ask how long it takes to get from a matched role to a salary bid. A vague promise to move quickly does not answer it. On the company side, the engineer should ask whether the team calls APIs, fine-tunes models, or trains from scratch, and whether its infrastructure supports productive work from day one. The engineer should also ask how the interview works and whether it allows AI tools. These answers reveal whether the network has done diligence on the company.
A network should be able to answer without assigning that homework back to the engineer. It screens rigorously, moves at a pace calibrated to how quickly strong candidates leave processes, delivers salary bids upfront, and knows the companies it surfaces. Its answers should arrive before the engineer has to ask. A network that cannot provide them has not earned the time required for a single role.